GLM‑5.3‑Flash: Multimodal open-weights model running on Swiss infrastructure
29.09.2026 | News | Luca Albrecht
The models features at a glance:
- Mixture-of-Experts architecture: 320 billion parameters, 18 billion active per token
- Context window: up to 262'144 tokens
- Hybrid attention (sparse + linear) reduces computational cost for long inputs
- OpenAI-compatible API, hosted entirely in Switzerland
- Areas of application: software development, debugging, large-scale document and image analysis, agent-based workflows
GLM-5.3-Flash is the latest addition to our AI on Demand model range. The model utilises a mixture-of-experts architecture with 320 billion parameters, although only around 18 billion are active per token. By combining sparse and linear attention, computational costs are reduced for very long contexts, enabling the model to process a context window of up to 262'144 tokens.
The broad context enables the analysis of extensive document collections, lengthy conversation histories or complex technical specifications. At the same time, customers can control the ‘thinking budget’ and adapt the depth of reasoning to the task at hand, ranging from rapid preliminary analysis to in-depth, multi-stage deliberations.
The entire process takes place on our Swiss infrastructure, ensuring that data remains in Switzerland and meets our high standards of data protection and security. Access is via a standardised OpenAI-compatible API, which can be seamlessly integrated into existing applications, development environments and agent-based systems.
Typical areas of application include software development (code analysis, debugging, automated refactoring), the processing of large volumes of data, image and document analysis, and agent-based workflows, in which the model utilises external tools and coordinates multi-stage tasks. We handle operation, monitoring and support, so that our customers can focus on integrating AI into their processes.
More News
29.09.2026 | News
GLM‑5.3‑Flash: Multimodal open-weights model running on Swiss infrastructure
We have recently made the GLM-5.3-Flash model available, a native multimodal Open-Weights model from Z.ai for text and image processing, programming…
18.09.2026 | Events
Silver Sponsor at Swiss Cloud Native Day 2026
A day packed with cloud innovation, fascinating talks and valuable connections. We were there as a Silver Sponsor at Cloud Native Day 2026.
17.09.2026 | Events
Retrospection Open Source Open Future in Zurich
On Wednesday, the 16th of September 2026, stepping stone AG hosted its annual partner, customer and networking event at Amboss Rampe in Zurich,…
07.09.2026 | Events
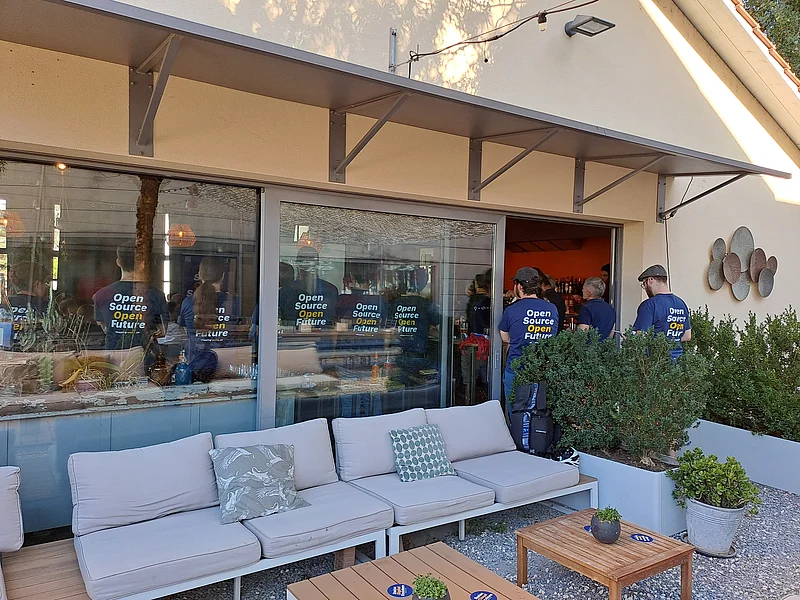
Retrospection Open Source Open Future in Bern
On Friday, the 4th of September 2026, stepping stone AG held its annual partner, customer and networking event at Café Bar Schichtwechsel in…

14.08.2026 | News
New GPU nodes in our data centres
On 11 August 2026, four new GPU nodes arrived at our premises and were installed in our data centre on the very same day.

14.08.2026 | Events
Open Source Open Future 2026: Registration is now open for the Agentic AI event
Registration has been open since 7 August 2026. We look forward to receiving your registration and to welcoming you in person at one of the two…